Does the Audio-to-Text Tool Read an Embedded Subtitle Track?
In these two tests, the SRT output follows the spoken audio rather than copying the embedded subtitle sentence.
Last updated: November 3, 2026.
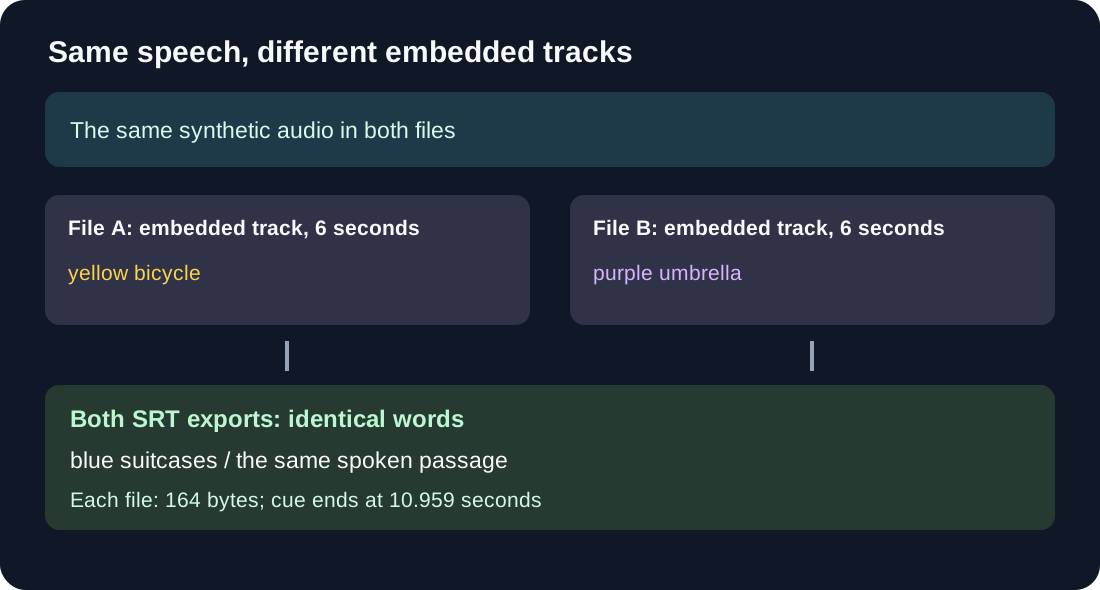
The two MP4 files contain the same synthetic speech and different embedded subtitle tracks. We selected English and SRT in the audio-to-text tool for each file.
| Material | Time | Embedded subtitle track | Actual output | Difference |
|---|---|---|---|---|
| File A | First 6 seconds | EMBEDDED ONLY: The yellow bicycle is outside gate seven. | The blue suitcases in room 14. Please keep the receipt with a silver key These words come from 'the audio', not this subtitle track | No complete sentence from the embedded track appears in the output. |
| File B | First 6 seconds | EMBEDDED ONLY: The purple umbrella is beside door eleven. | The blue suitcases in room 14. Please keep the receipt with a silver key These words come from 'the audio', not this subtitle track | No complete sentence from the embedded track appears in the output; its output is identical to File A. |
With the same speech held constant, changing the embedded sentence from a yellow bicycle at gate seven to a purple umbrella at door eleven did not change the exported sentence in these two runs. Both exports retained the audio-based wording about blue suitcases and room 14 instead of reproducing either complete embedded sentence. Each exported cue ends at 10.959 seconds, whereas both embedded cues end at 6 seconds and each input audio stream measures 10.960 seconds; the returned cue follows almost the entire audio duration rather than the embedded cue duration. Neither exported file contains the distinctive words "yellow bicycle" or "purple umbrella" from its corresponding embedded track; the result text contains the same speech-based passage in both files. The two downloaded files are byte-for-byte identical, with a single timestamped block in each export. This is a controlled comparison of two containers made from one synthetic recording, so changing the captions does not create a second speaker or an independent speech sample. It shows what happened for these inputs, without establishing behavior for every embedded subtitle format.
The 10.959-second cue end is recorded in the two downloadable SRT files hosted at reelscriptly.com, checked on November 3, 2026. The 10.960-second audio-stream durations were measured from the two input files with FFprobe on November 3, 2026; the 0.001-second difference does not establish how the tool chooses its boundaries.
Both outputs were 164 bytes when retrieved from reelscriptly.com on November 3, 2026: output A and output B. Both runs showed the same completion status, but completion is not evidence that the speech was transcribed correctly. In this test, the output changed "suitcase is" to "suitcases" and "the silver key" to "a silver key."
To retain an existing track's wording, inspect or extract that track with a tool designed for that task. To make a speech draft, use the audio transcription tool and check the result against the recording. These observations apply only to these files and runs.
Compare the follow-up test with two embedded subtitle tracks in reversed order.
By ReelScriptly · Last content update: